If an AI crawler cannot read the site, that AI will not cite you. But not every crawler is there to cite you: some read only to train models. The AI bots tab tells the two apart and writes the robots.txt for you.
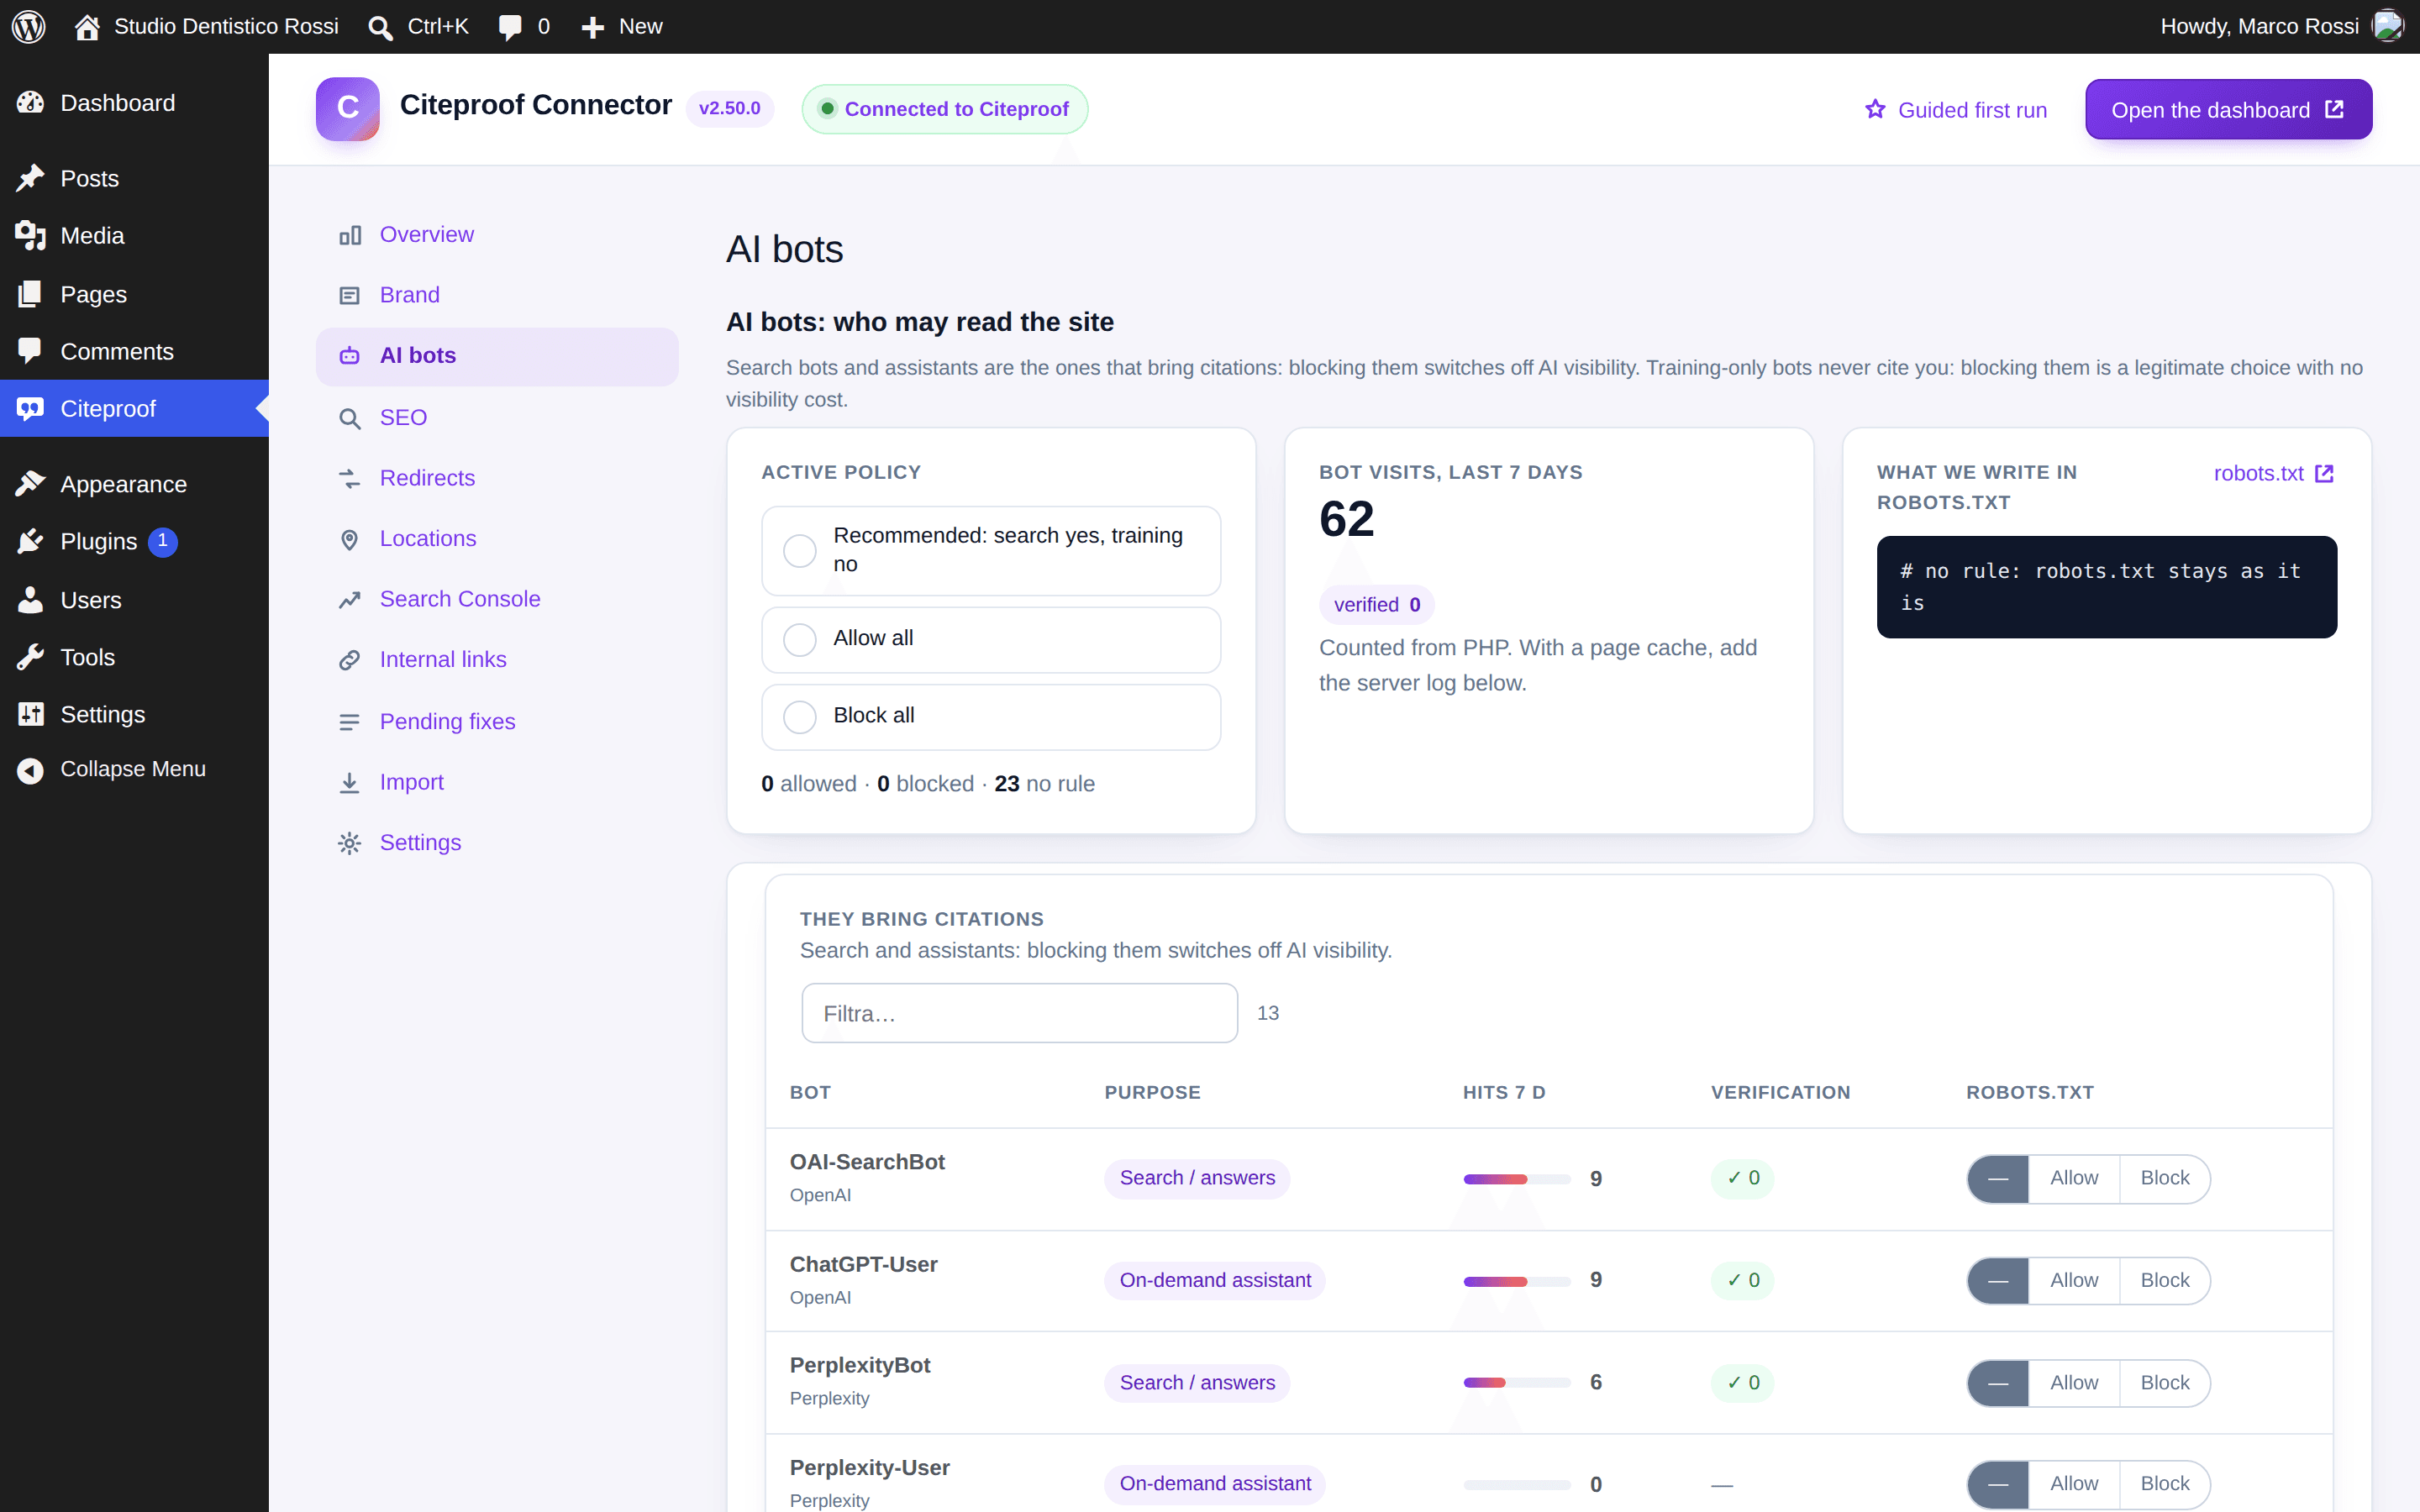
The three policies
- Recommended: search yes, training no — lets search bots and assistants through, blocks training-only bots.
- Allow all — no rule: robots.txt stays as it is.
- Block all — no AI crawler in the catalogue may read.
The right column shows exactly what the plugin writes into robots.txt; the link opens it.
Bot by bot
The table lists every crawler in the catalogue (OpenAI, Perplexity, Anthropic, Google, Microsoft, Apple, Amazon, Meta, ByteDance, Common Crawl and more) with its purpose (Search / answers, Assistant for the user, Training), the visits over the last seven days and the Allow / Block segment to override the policy on a single bot. A per-bot rule wins over the preset.
Blocking a training bot costs you no citations. Blocking a search bot or an assistant does: the plugin says so on the row.
Visits and verification
The plugin records AI crawler visits while WordPress serves pages and, for the bots that publish their addresses (OpenAI, Perplexity, Google, Bing, Apple, Amazon), verifies the IP: the Verify column says how many visits really came from the declared bot. Whoever pretends to be GPTBot to copy content stays out of the verified counts.
With a page cache PHP does not see every request: at the bottom of the tab you can point to the server log (Apache/Nginx) and the plugin reads it, also on sites behind a cache.
Where the data goes
Visits feed the Overview chart, the dashboard widget, the Bot activity page of the dashboard and the monthly proof. The local log keeps the last 300 visits.
If I block GPTBot do I lose ChatGPT?
No. GPTBot is OpenAI's training crawler. ChatGPT cites through OAI-SearchBot and ChatGPT-User: let those two through and block GPTBot without losing citations.
Do bots respect robots.txt?
The ones in the catalogue say they do, and for the big vendors the verified visits confirm it. A bot that ignores robots.txt has to be stopped at the server or CDN, not by the plugin.